Reading Your AI Bill Before It Reads You
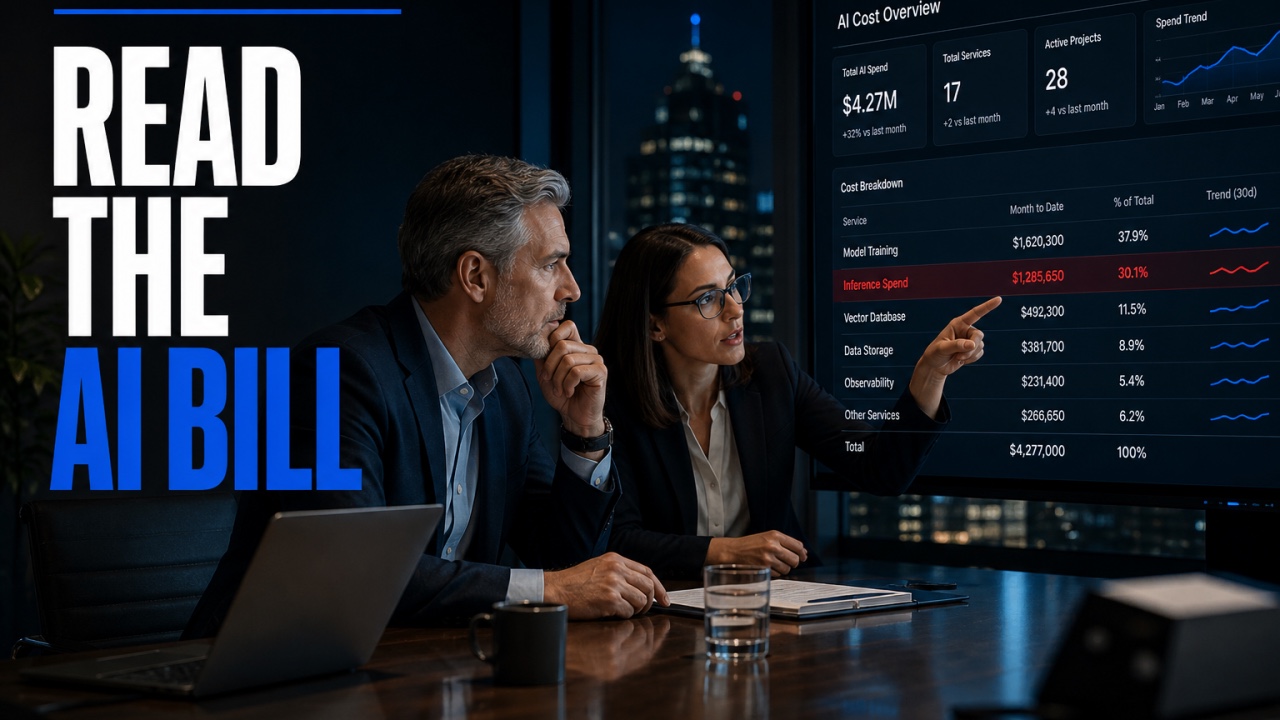
The first AI bill is a surprise. The second one is a problem. The third one is a meeting with finance.
The pattern is everywhere. The team builds the AI feature, estimates the cost from the demo, and ships. The demo used five requests. Production uses five thousand. The demo prompt was short. The production prompts carry the whole context. The demo ran for an afternoon. Production runs for a month. The bill arrives, and it's not the bill anyone budgeted for.
The AI bill is different from the cloud bill in one important way: the cost is attached to the work, and the work is attached to the design. Every prompt, every context, every retry, every model call is a line item with your fingerprints on it. The bill isn't a mystery. It's a mirror. Learning to read it is the difference between running AI and being run by it.
The unit economics of a request
The AI bill is built from the unit: the cost of one request. And the cost of one request is built from things you control.
The model choice is the biggest lever. The frontier model costs more per token than the small model — sometimes ten times more. The tiering discipline from earlier applies here: the request that a small model handles fine is a request paying first-class fare. The bill is where that decision shows up.
The context length is the hidden lever. Every request carries the context — the system prompt, the history, the documents, the conversation. The context is charged on every request, even when it doesn't change. The request that carries a five-thousand-token context costs five thousand tokens of input on every single call, and the team that doesn't watch context size is paying for the same luggage on every flight.
The retry pattern is the quiet multiplier. The integration that retries on failure, the agent that loops until it's satisfied, the pipeline that re-runs the whole batch when one item fails — each retry is a full-price request. A system that looks cheap per request can be expensive per completed task if the retries are hidden.
The unit is the request, and the request is a decision: model, context, retries. Read the unit, and the bill stops being a surprise.
The cost per task, not per request
The bill shows requests. The business cares about tasks. The gap between the two is where the real economics live.
The request is the raw unit. The task is the completed outcome — the ticket resolved, the order processed, the report generated. One task can cost one request or ten, depending on the design. The agent that burns ten requests to finish one task isn't cheaper than the workflow that does it in two. It just looks better in the request count.
The metric that matters is cost per completed task, and it's the number that should be on the dashboard next to the other five signals. Cost per task is the business-facing number — the one that answers “what is this AI actually costing us to do the work.” It's also the number that catches the design problems the request count hides: the bloated context, the retry storm, the model that's too expensive for the task.
The guardrails that stop the surprise
The bill is managed with guardrails, and they're the same shape as the guardrails on any other budget.
The budget alert comes first. A threshold on monthly spend, with an alert when the run rate crosses it. The alert fires before the bill, not after. The threshold isn't a limit — it's a signal that the spend is behaving differently than planned, and different behavior is information.
The per-task cap comes second. A maximum cost per task, enforced at the design level. The task that's about to burn through the cap fails fast instead of running the meter. The cap is the technical version of the budget — it stops the runaway before it reaches the bill.
The quarterly cost review comes third. The same review cadence as the data-health review: walk the cost per task by task type, find the tasks whose unit cost drifted up, and fix the cause. The review is where the guardrails get tuned and the lessons get learned — the task that migrated up a tier, the context that bloated, the retry pattern that emerged.
The question that reframes the bill
When the next AI bill arrives, ask one question before you react: what did this buy?
The bill that bought completed tasks at a reasonable cost per task is a good bill, regardless of the total. The bill that bought requests that didn't become outcomes — the retries, the loops, the dead ends — is a bad bill, regardless of the total. The total is the headline. The cost per completed task is the truth.
The AI bill is readable. Model choice, context size, retry patterns, cost per completed task, and guardrails that catch the drift. Build the unit economics into the design, put the cost per task on the dashboard, and the bill stops being the monthly surprise and becomes what it actually is: the report card on your AI design. Read it, tune it, and the bill does what it's supposed to — it tells you where the system is wasting money, before finance does.
Think this argument fits your event? Tell me about the room — the calendar is selective.
Start a conversation