When the Tire Shop Closes in Ten Minutes: Contingency Plans Are Fallbacks, Not Forecasts
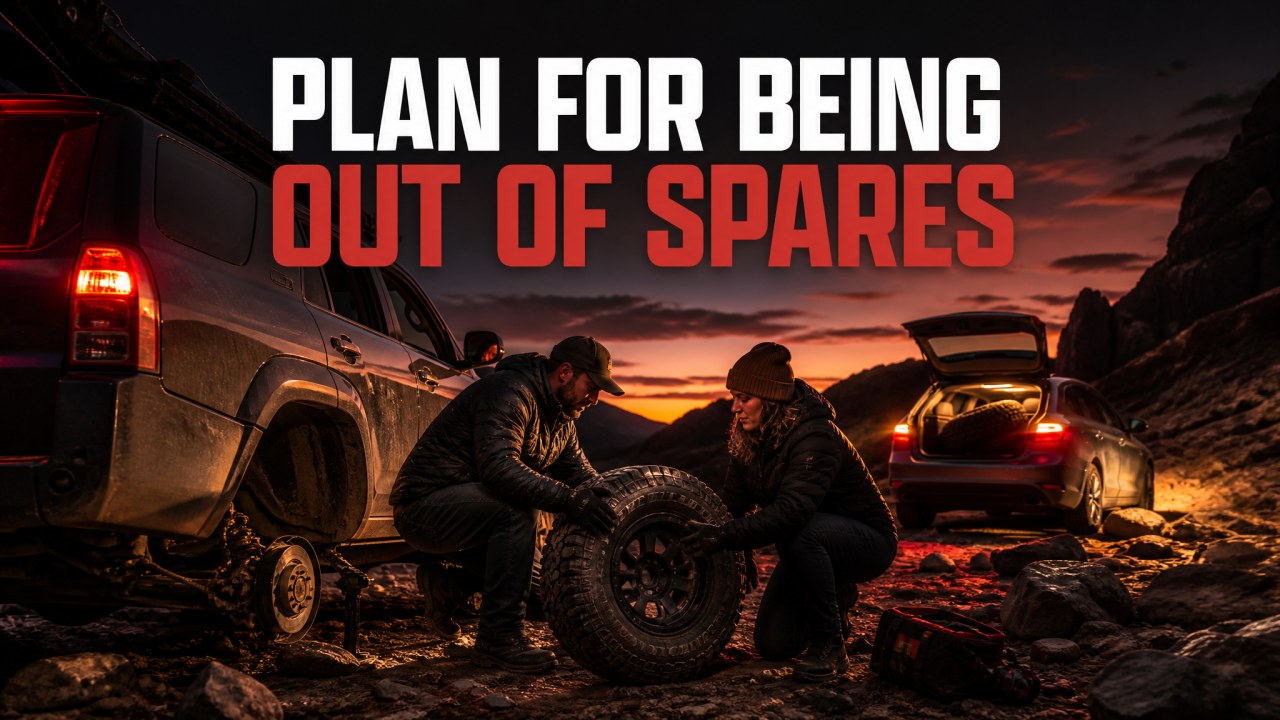
We were in the rock garden at Badlands when the rear passenger tire got destroyed. Already out of spares. Everyone's on their phone, searching for a replacement, and somebody finds a tire shop that has the size we need.
It closes in ten minutes.
And the guy makes it very clear he is not staying past closing.
So I call the tire shop and pay for the tire over the phone. I arrange an Uber to the shop, talk to the driver, promise a serious tip, and he agrees to bring the tire to the park. Then I call the park office — we didn't know the park well — and ask them to hold the tire at the front if we missed the driver. The staff reaction was entertainment. They'd never seen a tire delivered by Uber. The security guy just asked how in the hell we arranged that.
The tire got to us. We field-mounted it on the rim, which is not recommended, and made it back to the tow rigs before the park closed.
Here's what that day was actually about: you don't plan for the tire to blow. You plan for being out of spares.
The tire failing was never in our control. Being out of spares was a decision we'd made earlier — a single point of failure we carried into the park. That's the mistake worth naming first, because it's the one that created the whole adventure. We should have had a second spare, or a repair kit, or both. Redundancy is the boring part of the plan, and it's the part that actually prevents incidents.
But incidents happen anyway. And when they do, the plan isn't a forecast — it's a chain of fallbacks. Look at what each link in our chain cost: a phone call to pay for the tire, a rideshare request, a promise to a park office. Each one was trivial to set up. Each one was fast to trigger. And each one was a path to the same outcome, so if any single link broke, the next one still got us home.
That's the structure worth copying. Not one elaborate recovery plan. Several cheap fallbacks, arranged in parallel, each of which works alone. The shop could have said no. The driver could have bailed. The office could have missed us. Any one of those fails and we still had a path.
In incident response we do the opposite: we write one detailed runbook and call it a day. Then the runbook's single point of failure — the one person who knows how to run it, the one tool that's down, the one vendor that's unreachable — becomes the second incident.
The tire was the problem. The system around it was the fix. Build the chain of fallbacks before you need it, and test each link while it's cheap.
Think this argument fits your event? Tell me about the room — the calendar is selective.
Start a conversation