Your AI's Confidence Score, Translated for Humans
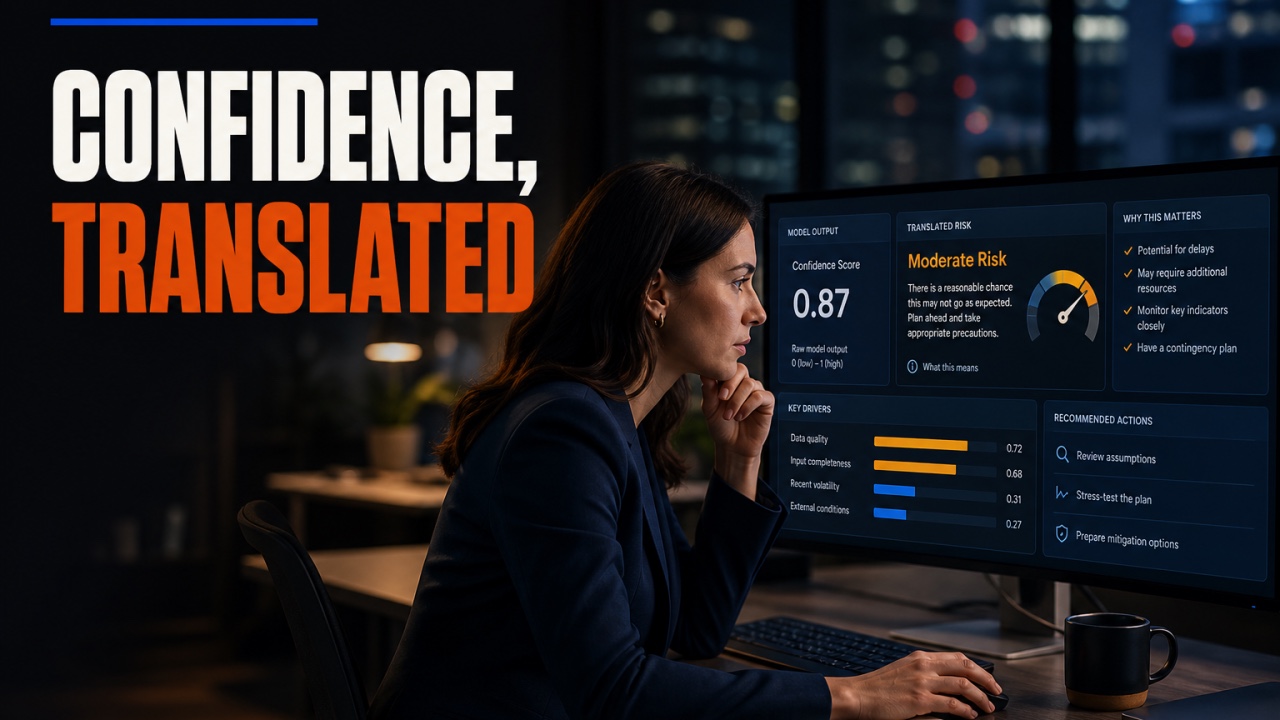
Your AI has a confidence score. Your operators don't know what it means. So it might as well not exist.
The engineers built it. The dashboard shows it. And somewhere in your organization, a person looking at an AI-generated answer is trying to decide whether 0.87 means “pretty sure” or “basically certain.” They're guessing. When people guess about confidence, they make the worst possible calls — they trust the wrong things and second-guess the right ones.
The confidence score is the single most useful thing your AI can tell you, and it's useless if the people acting on it can't read it.
The translation problem
Here's what the number actually is: a model's estimate of how likely its answer is to be correct, based on how well the answer fits what it has seen. That's a useful signal. It's also a number that means nothing to someone whose job is answering a customer, moving an order, or approving a payment.
The problem isn't the score. It's the absence of a translation layer. The engineer sees 0.87 and knows what it implies. The operator sees 0.87 and sees a mystery. So the operator falls back on intuition — and intuition about a number they don't understand is worse than no number at all.
A confidence score that isn't translated into an action is noise. The job isn't to display the number. It's to tell people what to do with it.
Translate to actions, not numbers
The fix is to stop presenting confidence as a number and start presenting it as a decision. Three buckets. That's all the granularity a human acting in real time needs.
High confidence means: act on this. It's the answer to a routine question, it matches the pattern, and the cost of being wrong is low. Don't double-check it. The whole point of high confidence is that checking it wastes the time AI was supposed to save.
Medium confidence means: use it, but verify the parts that matter. The answer is probably right, but there's a real chance something specific is off. The instruction isn't “check everything” — that's high effort and people won't do it. It's “check the numbers, the dates, the names” — the parts that, if wrong, cause actual damage.
Low confidence means: don't act. Escalate or redo. This is the bucket that protects you. When the AI isn't sure, acting on its answer is gambling, and gambling with customer money, customer data, or compliance is how small errors become big ones.
Three buckets, three verbs: act, verify, escalate. No decimals.
The one question that makes it concrete
The cleanest way to build the translation layer is to answer one question for every task: what does wrong cost?
That's the question that turns a number into a decision. For a routine status answer, wrong costs nothing, so even a medium confidence answer is fine to act on. For a price quote, wrong costs an account, so only high confidence answers get acted on and everything else gets checked. For a compliance answer, wrong costs a regulator, so nothing gets acted on without a human verifying the source.
Same model. Same confidence score. Three different thresholds, because the cost of error is different. The confidence score doesn't change. What changes is what you do with it.
This is also the answer to the question operators will ask: “why does the AI sometimes act on 0.7 and sometimes not?” Because the stakes are different. That's the whole explanation, and it's one a six-year-old — and a CFO — can understand.
Where the translation lives
The translation has to live where the decision happens, not in a training deck.
For humans in the loop, it lives in the interface. The AI answer comes with a color, not a number — green, yellow, red — and the color maps to a verb. Act. Verify. Escalate. The operator doesn't read a score. They read a traffic light.
For the automated pipeline, it lives in the threshold. The system acts on green, flags yellow for review, and routes red to a human. The thresholds get set per task, using the cost-of-error answer. And they get reviewed, because the calibration changes as the model improves.
The score stays in the background, where the engineers use it to tune the system. The operators get the translation.
Why this matters more than the model
Here's the uncomfortable part. The difference between a company that benefits from AI and one that gets burned by it is rarely the model. It's the decision layer around the model. Two companies can run the same model with the same accuracy. One uses the confidence signal to route work correctly, and the other ignores it or misreads it. One wins, one gets burned.
The confidence score is the steering wheel. You can build the best engine in the world, and it's useless if nobody knows which way to turn the wheel.
Three buckets. Act, verify, escalate. And one question — what does wrong cost — that sets the thresholds for every task. That's the whole translation. Your operators don't need to understand the model. They need to know what to do with the answer, and the confidence score, properly translated, is exactly what tells them.
The number is for the engineers. The verb is for the humans. Ship the verb.
Think this argument fits your event? Tell me about the room — the calendar is selective.
Start a conversation